Back to Portfolio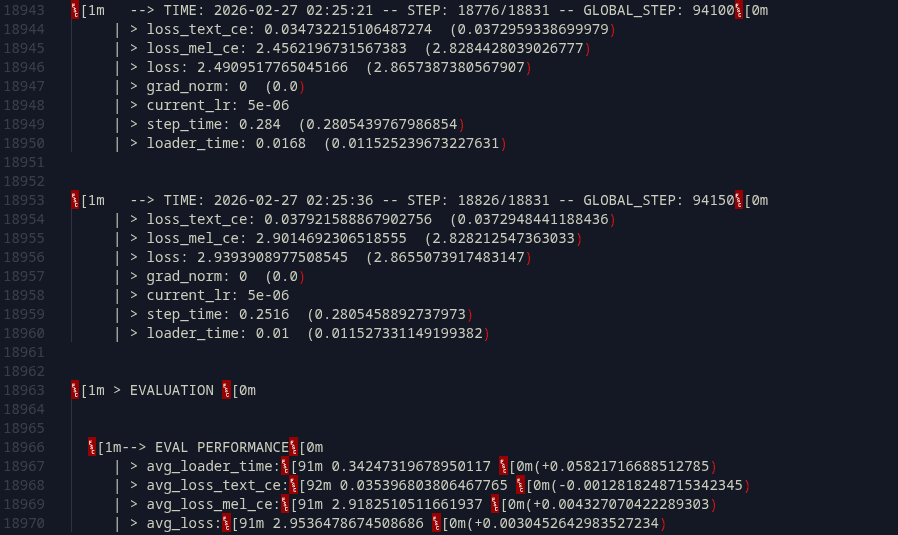
AI Engineer
Fine Tuning Model AI TTS XTTS-v2
Fine-tuned the XTTS-v2 model to enable and improve Indonesian language speech synthesis. Sourced thousands of hours of clean Indonesian audio datasets from Hugging Face, executing 5 training epochs utilizing PyTorch and CUDA. Containerized the entire training pipeline in Docker to ensure environment reproducibility.
Preview Unavailable
This project is not currently deployed online and does not have a video walk-through demo.
Explore Source Code↗Technologies Used
PythonPyTorchXTTS-v2Hugging FaceCUDADocker